Industry packs

Clinical Trials industry pack

Synthetic study, subject, visit, safety, randomisation and central-lab test data

Preview only · not activatable yet Version 1.0.0 · Complete

Everything on this page works without an account. Prefer a conversation? Request a demo (optional). Missing something? Request a feature.

This pack is installed and passes DataNivra’s pack conformance kit through the real engine, but it cannot be activated yet: no plan includes it yet, the standard agent image does not ship it, the control-plane catalogue does not list it and the hosted sandbox has no synthetic estate for it. You can explore its synthetic records, masking and scenarios on this page and in the browser demo. Tell us if you need it: demand decides which packs become activatable next.

Problems this pack solves

Masked data that still joins across 5 systems

8 cross-system relationships link central_lab, ctms, edc, irt and safety; the pack's masking keeps one pseudonym per identity on every side. For example, edc.subjects.subject_id and irt.randomisations.subject_ref get the same pseudonym.

The cases production samples rarely contain

9 ready-made scenarios generate them on demand, for example: subjects who fail eligibility at screening, with the criterion that was not met; serious, severe adverse events with safety case reports, some unexpected; treatment arms revealed for medical emergencies, with time and reason recorded.

Sensitive fields found and masked before anyone sees them

43 columns across 14 entities are classified (direct identifier, PHI, PII, quasi identifier and sensitive) and covered by 3 masking templates you review and approve.

Evidence that each dataset is fit to use

2 certification presets check masking coverage, referential integrity, orphans and row counts before a dataset can be provisioned; a failed dataset is never provisioned.

Entities and relationships

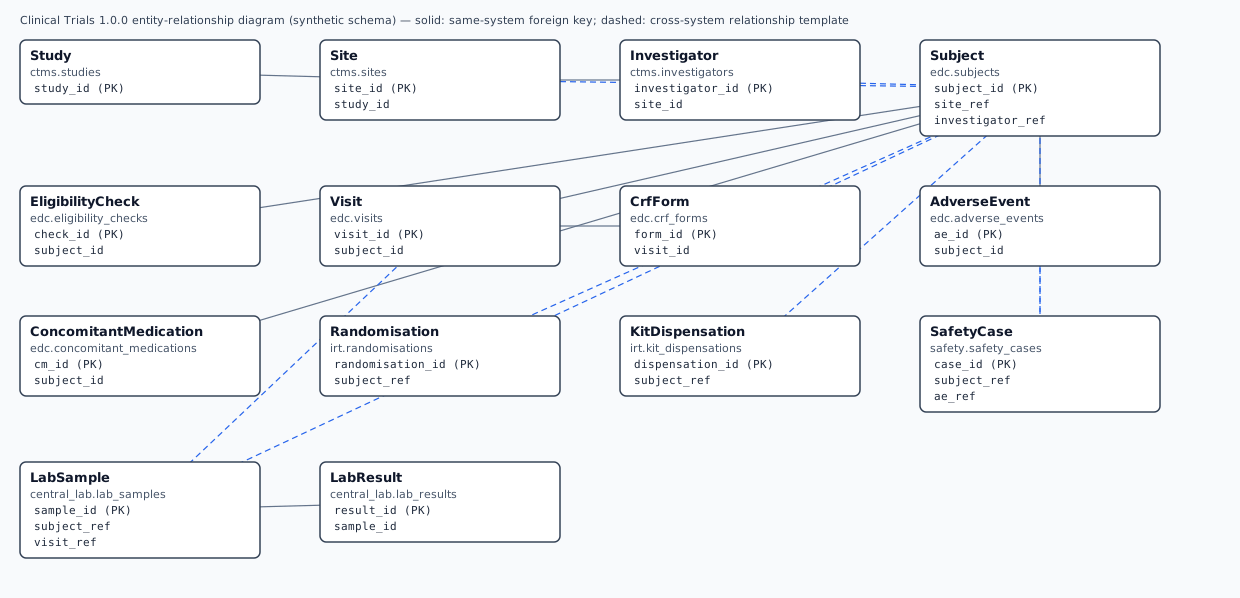
14 entities across 5 source systems, generated from the pack’s own entity model.

Entity graph of the Clinical Trials pack14 entities in 5 systems (ctms, edc, irt, safety, central_lab) linked by 16 relationships, 8 of them across systems. The table after the graph lists every relationship.ctmsedcirtsafetycentral_labStudy (ctms.studies)Studyctms.studiesSite (ctms.sites)Sitectms.sitesInvestigator (ctms.investigators)Investigatorctms.investigatorsSubject (edc.subjects)Subjectedc.subjectsEligibilityCheck (edc.eligibility_checks)EligibilityCheckedc.eligibility_checksVisit (edc.visits)Visitedc.visitsCrfForm (edc.crf_forms)CrfFormedc.crf_formsAdverseEvent (edc.adverse_events)AdverseEventedc.adverse_eventsConcomitantMedication (edc.concomitant_medications)ConcomitantMedicati…edc.concomitant_medica…Randomisation (irt.randomisations)Randomisationirt.randomisationsKitDispensation (irt.kit_dispensations)KitDispensationirt.kit_dispensationsSafetyCase (safety.safety_cases)SafetyCasesafety.safety_casesLabSample (central_lab.lab_samples)LabSamplecentral_lab.lab_samplesLabResult (central_lab.lab_results)LabResultcentral_lab.lab_results
Arrows point from the referencing entity to the one it references. Solid: a foreign key inside one system. Dashed: a cross-system relationship — the pack keeps the same pseudonym on both sides, so masked data still joins.
All 16 relationships as a table
Relationships of the Clinical Trials pack
EntityReferencesColumnsKind
SiteStudystudy_id → study_idWithin a system
InvestigatorSitesite_id → site_idWithin a system
EligibilityCheckSubjectsubject_id → subject_idWithin a system
VisitSubjectsubject_id → subject_idWithin a system
CrfFormVisitvisit_id → visit_idWithin a system
AdverseEventSubjectsubject_id → subject_idWithin a system
ConcomitantMedicationSubjectsubject_id → subject_idWithin a system
LabResultLabSamplesample_id → sample_idWithin a system
SubjectSitesite_ref → site_idAcross systems (pack relationship template)
SubjectInvestigatorinvestigator_ref → investigator_idAcross systems (pack relationship template)
RandomisationSubjectsubject_ref → subject_idAcross systems (pack relationship template)
KitDispensationSubjectsubject_ref → subject_idAcross systems (pack relationship template)
SafetyCaseSubjectsubject_ref → subject_idAcross systems (pack relationship template)
SafetyCaseAdverseEventae_ref → ae_idAcross systems (pack relationship template)
LabSampleSubjectsubject_ref → subject_idAcross systems (pack relationship template)
LabSampleVisitvisit_ref → visit_idAcross systems (pack relationship template)

Realistic synthetic records

Synthetic data. Every record on this page is synthetic, generated from a fixed seed by the pack's own generator; masked values come from the real masking engine.

Subject — edc.subjects (synthetic)
subject_id sensitivesite_refinvestigator_refscreening_number sensitiveinitials sensitivebirth_year sensitivesex sensitiveethnicity sensitiveconsent_date sensitivestatusscreen_failure_reasonwithdrawal_reason
Z101-0001ZSI-01012SCR-0000001KV1996MNOT_REPORTED2024-08-17COMPLETED——
Z102-0001ZSI-01023SCR-0000002XW1968MNOT_REPORTED2025-03-26ENROLLED——

Masking: before and after

Template Linked clinical-trial test data (CT_LINKED_TEST_DATA) applied to a synthetic Subject record from edc.subjects.

Synthetic Subject record before and after masking
ColumnClassified asBefore (synthetic)After masking
subject_idDirect identifierZ101-0001X746-6163
screening_numberDirect identifierSCR-0000001FDX-7019580
initialsPII, Direct identifierKV[REDACTED]
birth_yearQuasi identifier19961997
sexQuasi identifierM[REDACTED]
ethnicitySensitiveNOT_REPORTED[REDACTED]
consent_datePHI, Quasi identifier2024-08-172024-09-01

Same pseudonym in two systems. The identifier Z101-0001 appears in edc.subjects.subject_id and in irt.randomisations.subject_ref. Both become X746-6163, so the masked systems still join (relationship CT_RANDOMISATION_SUBJECT).

Masked with a fixed public sample key so this example is reproducible; your data is masked with your own key, referenced from your secret store.

Synthetic scenarios you can run

11 runnable scenarios. Preview them in your browser without an account; the hosted sandbox opens when the pack becomes activatable.

Routine conduct

Normal CT_ROUTINE_CONDUCT

Ordinary study conduct: enrolled subjects, in-window visits, forms, labs, randomisation and kits

Everyday, valid records: the baseline most tests expect. Children per parent record: 1–3.

Preview in the browser demo: Routine conduct

Screen failures

Rare CT_SCREEN_FAILURES

Subjects who fail eligibility at screening, with the criterion that was not met

Valid but uncommon business situations that production samples often miss. Children per parent record: 1–3.

Preview in the browser demo: Screen failures

Serious adverse events

Rare CT_SERIOUS_ADVERSE_EVENTS

Serious, severe adverse events with safety case reports, some unexpected

Valid but uncommon business situations that production samples often miss. Children per parent record: 1–3.

Preview in the browser demo: Serious adverse events

Emergency unblinding

Rare CT_EMERGENCY_UNBLINDING

Treatment arms revealed for medical emergencies, with time and reason recorded

Valid but uncommon business situations that production samples often miss. Children per parent record: 1–2.

Preview in the browser demo: Emergency unblinding

Withdrawals

Rare CT_WITHDRAWALS

Subjects who withdrew consent or were lost to follow-up, with a reason

Valid but uncommon business situations that production samples often miss. Children per parent record: 1–3.

Preview in the browser demo: Withdrawals

Sample problems

Rare CT_SAMPLE_PROBLEMS

Haemolysed, lost or insufficient central-lab samples without a usable result

Valid but uncommon business situations that production samples often miss. Children per parent record: 1–3.

Preview in the browser demo: Sample problems

Missed visits

Rare CT_MISSED_VISITS

Missed visits (no date) and visits outside their protocol window

Valid but uncommon business situations that production samples often miss. Children per parent record: 2–4.

Preview in the browser demo: Missed visits

Visit window edge

Boundary CT_VISIT_WINDOW_EDGE

Completed visits exactly at the first or last day of their protocol window

Values at the edges of valid ranges (limits, thresholds, extremes). Children per parent record: 2–4.

Preview in the browser demo: Visit window edge

Lab reference limits

Boundary CT_LAB_REFERENCE_LIMITS

Lab results exactly at the low or high reference limit (flagged normal)

Values at the edges of valid ranges (limits, thresholds, extremes). Children per parent record: 1–3.

Preview in the browser demo: Lab reference limits

Duplicate lab transfers

Duplicate CT_DUPLICATE_LAB_TRANSFERS

Lab results delivered twice by the central-lab data transfer under new ids

Records that repeat others under new keys (clean-up and matching tests). Children per parent record: 2–4.

Preview in the browser demo: Duplicate lab transfers

Long running study

Historical CT_LONG_RUNNING_STUDY

A multi-year, referentially intact study with complete records and no gaps

Old records for archive, migration and retention tests. Children per parent record: 1–3.

Preview in the browser demo: Long running study
Negative tests, kept apart. This scenario produces deliberately broken data for error handling and never passes certification as valid data:

  • CT_BROKEN_REFERENCES — Dangling cross-system references and invalid values for error-handling tests

Sample schemas and representative outputs

The schema the pack expects in each system (also as CREATE TABLE DDL in the downloads). A run produces a masked or synthetic dataset with the same tables, a certification report with the gates of the chosen preset, and an evidence manifest with checksums — the rows stay in your environment.

Study — ctms.studies · 8 columns

A (fictional) interventional study run under one protocol by a sponsor.

ColumnTypeRequiredSensitive classes
study_id (key)VARCHAR(12)Yes—
protocol_numberVARCHAR(16)Yes—
sponsor_codeVARCHAR(16)Yes—
phaseVARCHAR(8)Yes—
therapeutic_areaVARCHAR(24)Yes—
blindingVARCHAR(16)Yes—
statusVARCHAR(20)Yes—
planned_enrolmentINTYes—
Site — ctms.sites · 6 columns

An investigational site taking part in a study.

ColumnTypeRequiredSensitive classes
site_id (key)VARCHAR(10)Yes—
study_idVARCHAR(12)Yes—
site_numberINTYes—
country_codeVARCHAR(2)Yes—
statusVARCHAR(10)Yes—
activated_onDATEYes—
Investigator — ctms.investigators · 8 columns

A principal investigator, sub-investigator or coordinator at a site (personal data too).

ColumnTypeRequiredSensitive classes
investigator_id (key)BIGINTYes—
site_idVARCHAR(10)Yes—
given_nameVARCHAR(64)YesPII, Direct identifier
family_nameVARCHAR(64)YesPII, Direct identifier
emailVARCHAR(128)NoPII, Direct identifier
phoneVARCHAR(32)NoPII, Direct identifier
registry_numberVARCHAR(16)NoPII, Direct identifier
roleVARCHAR(24)Yes—
Subject — edc.subjects · 12 columns

A study participant known by a per-study subject number (the natural subset root).

ColumnTypeRequiredSensitive classes
subject_id (key)VARCHAR(12)YesDirect identifier
site_refVARCHAR(10)Yes—
investigator_refBIGINTYes—
screening_numberVARCHAR(12)YesDirect identifier
initialsVARCHAR(3)NoPII, Direct identifier
birth_yearINTNoQuasi identifier
sexVARCHAR(1)NoQuasi identifier
ethnicityVARCHAR(16)NoSensitive
consent_dateDATEYesPHI, Quasi identifier
statusVARCHAR(20)Yes—
screen_failure_reasonVARCHAR(20)No—
withdrawal_reasonVARCHAR(20)No—
EligibilityCheck — edc.eligibility_checks · 6 columns

One inclusion or exclusion criterion assessed at screening.

ColumnTypeRequiredSensitive classes
check_id (key)BIGINTYes—
subject_idVARCHAR(12)YesDirect identifier
criterion_codeVARCHAR(4)Yes—
criterion_typeVARCHAR(10)Yes—
metBOOLEANYes—
assessed_onDATEYesPHI, Quasi identifier
Visit — edc.visits · 7 columns

A protocol visit of a subject (planned on a study day, done within a window or not).

ColumnTypeRequiredSensitive classes
visit_id (key)BIGINTYes—
subject_idVARCHAR(12)YesDirect identifier
visit_codeVARCHAR(16)Yes—
planned_dayINTYes—
actual_dayINTNo—
visit_dateDATENoPHI, Quasi identifier
statusVARCHAR(16)Yes—
CrfForm — edc.crf_forms · 9 columns

A case report form page completed for a visit.

ColumnTypeRequiredSensitive classes
form_id (key)BIGINTYes—
visit_idBIGINTYes—
form_codeVARCHAR(16)Yes—
systolic_bpINTNo—
diastolic_bpINTNo—
sdv_statusVARCHAR(14)Yes—
open_queriesINTYes—
lockedBOOLEANYes—
site_commentVARCHAR(300)NoPHI, Sensitive
AdverseEvent — edc.adverse_events · 11 columns

An adverse event recorded on the CRF (serious ones also become safety cases).

ColumnTypeRequiredSensitive classes
ae_id (key)BIGINTYes—
subject_idVARCHAR(12)YesDirect identifier
ae_term_codeVARCHAR(10)Yes—
verbatim_termVARCHAR(200)NoPHI, Sensitive
onset_dateDATEYesPHI, Quasi identifier
resolved_dateDATENoPHI, Quasi identifier
severityVARCHAR(10)Yes—
seriousBOOLEANYes—
causalityVARCHAR(12)Yes—
outcomeVARCHAR(14)Yes—
action_takenVARCHAR(18)Yes—
ConcomitantMedication — edc.concomitant_medications · 9 columns

A medication the subject takes alongside the study treatment.

ColumnTypeRequiredSensitive classes
cm_id (key)BIGINTYes—
subject_idVARCHAR(12)YesDirect identifier
drug_codeVARCHAR(10)Yes—
indicationVARCHAR(120)NoPHI, Sensitive
dose_amountDOUBLENo—
dose_unitVARCHAR(6)No—
start_dateDATEYesPHI, Quasi identifier
end_dateDATENoPHI, Quasi identifier
ongoingBOOLEANYes—
Randomisation — irt.randomisations · 9 columns

Randomisation of a subject to a (blinded) treatment arm, with any emergency unblinding.

ColumnTypeRequiredSensitive classes
randomisation_id (key)BIGINTYes—
subject_refVARCHAR(12)YesDirect identifier
randomisation_numberVARCHAR(10)YesDirect identifier
stratumVARCHAR(10)Yes—
treatment_armVARCHAR(8)YesSensitive
randomised_atTIMESTAMPYesPHI, Quasi identifier
unblinding_statusVARCHAR(10)Yes—
unblinded_atTIMESTAMPNoSensitive
unblinding_reasonVARCHAR(20)NoSensitive
KitDispensation — irt.kit_dispensations · 7 columns

An investigational-product kit dispensed to a subject at a visit.

ColumnTypeRequiredSensitive classes
dispensation_id (key)BIGINTYes—
subject_refVARCHAR(12)YesDirect identifier
kit_numberVARCHAR(12)YesSensitive, Direct identifier
visit_codeVARCHAR(16)Yes—
dispensed_onDATEYesPHI, Quasi identifier
units_dispensedINTYes—
units_returnedINTNo—
SafetyCase — safety.safety_cases · 10 columns

An individual case safety report raised for a serious adverse event.

ColumnTypeRequiredSensitive classes
case_id (key)BIGINTYes—
case_numberVARCHAR(14)YesDirect identifier
subject_refVARCHAR(12)YesDirect identifier
ae_refBIGINTYes—
received_onDATEYesPHI, Quasi identifier
seriousnessVARCHAR(20)Yes—
expectednessVARCHAR(10)Yes—
reporter_nameVARCHAR(96)NoPII, Direct identifier
narrativeVARCHAR(600)NoPHI, Sensitive
report_statusVARCHAR(10)Yes—
LabSample — central_lab.lab_samples · 8 columns

A specimen collected at a visit and shipped to the central laboratory.

ColumnTypeRequiredSensitive classes
sample_id (key)BIGINTYes—
accession_numberVARCHAR(12)YesDirect identifier
subject_refVARCHAR(12)YesDirect identifier
visit_refBIGINTYes—
specimen_typeVARCHAR(12)Yes—
collected_atTIMESTAMPYesPHI, Quasi identifier
received_atTIMESTAMPNoPHI, Quasi identifier
statusVARCHAR(20)Yes—
LabResult — central_lab.lab_results · 8 columns

One analyte result of a sample (invented ZLB-... analytes).

ColumnTypeRequiredSensitive classes
result_id (key)BIGINTYes—
sample_idBIGINTYes—
analyte_codeVARCHAR(8)Yes—
result_valueDOUBLENo—
unitVARCHAR(8)Yes—
reference_lowDOUBLEYes—
reference_highDOUBLEYes—
flagVARCHAR(2)Yes—

Compatible connectors

Verified with this pack version: PostgreSQL and Local files (Parquet / CSV). 17 more connectors are compatible by capability: they support what the pack needs, but have not been verified with this pack yet.

ConnectorStatus with Clinical Trials
Local files (Parquet / CSV)Verified with this pack
PostgreSQLVerified with this pack
Amazon S3 / S3-compatible storageCompatible by capability (not yet verified with this pack)
Apache Kafka (connector in preview)Compatible by capability (not yet verified with this pack)
Azure Blob Storage / Data Lake StorageCompatible by capability (not yet verified with this pack)
DatabricksCompatible by capability (not yet verified with this pack)
Generic SQL (SQLAlchemy)Compatible by capability (not yet verified with this pack)
Google BigQueryCompatible by capability (not yet verified with this pack)
HTTP APIs (connector in preview)Compatible by capability (not yet verified with this pack)
IBM Db2 (connector in preview)Compatible by capability (not yet verified with this pack)
Mainframe files (EBCDIC / copybook) (connector in preview)Compatible by capability (not yet verified with this pack)
MariaDBCompatible by capability (not yet verified with this pack)
Microsoft SQL ServerCompatible by capability (not yet verified with this pack)
MongoDB (connector in preview)Compatible by capability (not yet verified with this pack)
MySQLCompatible by capability (not yet verified with this pack)
Oracle DatabaseCompatible by capability (not yet verified with this pack)
Parquet filesCompatible by capability (not yet verified with this pack)
SnowflakeCompatible by capability (not yet verified with this pack)
SQLite (developer evaluation) (connector in preview)Compatible by capability (not yet verified with this pack)

Prerequisites and expected setup effort

You need

  • This pack is not in any plan yet.
  • One DataNivra agent inside your network (outbound HTTPS only) that ships Clinical Trials 1.0.0.
  • Read-only access to a compatible source (verified with this pack: PostgreSQL, Local files (Parquet / CSV)).
  • A non-production target environment the agent may write test data to.
  • A masking key in your own secret store, referenced as vault://…, azure-kv://… or env://… (DataNivra only ever sees the reference).
  • For production sources, a second person who approves policies (separation of duties).

A DataNivra agent that reports its installed industry packs (releases after agent 0.3.0); the control plane runs a pack job only on an agent holding the exact active pack version with the catalogued integrity digest.

Expected setup effort (estimates)

StepEstimate
Try the synthetic sandbox
No install: sign up and open the sandbox.
Minutes (estimate)
Install (or reuse) the agent
One Docker command or a Helm chart; outbound HTTPS only.
Under an hour (estimate)
Connect a source
Register a read-only source through the existing connector workflow.
Under an hour (estimate)
Review and approve policies
Create drafts from the Clinical Trials templates, review and approve them.
Under an hour (estimate)
First certified dataset
Run the first job; certification and evidence are produced automatically.
Minutes (estimate)

Certification presets in plain language

CT_STRICT

Every gate; full masking coverage; zero orphaned visits, forms, adverse events, medications, randomisations, kits, safety cases, samples or results; exact row counts. Default for masked clinical-trial test data.

  • Masking coverage of at least 100% of sensitive columns
  • No orphaned child records
  • Empty-value ratio may rise by at most 5%
  • Row counts must match exactly
16 gates it requires
  • POLICY_COVERAGE: every sensitive column is covered by an approved policy
  • MASKING_COMPLETION: masking finished on every covered column
  • REFERENTIAL_INTEGRITY: every reference still points at an existing record
  • SCHEMA_VALIDATION: the output schema matches the source schema
  • DATA_QUALITY: empty-value ratios stay within the preset’s drift limit
  • ROW_COUNT_RECONCILIATION: row counts match the plan within the tolerance
  • ORPHAN_DETECTION: no child record lost its parent
  • PROVENANCE: every row is tagged masked or synthetic
  • MANIFEST: a manifest lists every output table with checksums
  • POLICY_VERSION: the exact approved policy versions are recorded
  • ENGINE_VERSION: the engine version is recorded
  • CHECKSUMS: output checksums are recorded for later verification
  • IDENTITY_CONSISTENCY: linked identifiers got the same pseudonym in every system
  • SOURCE_READ_ONLY: the source was only read, never written
  • EGRESS_GUARD: no row-level data left the agent
  • CONNECTOR_HEALTH: the connectors stayed healthy during the run

CT_SCENARIO_TESTING

Every gate, with slightly relaxed NULL-ratio drift for scenario datasets whose study states (missed visits, lost samples, blinded randomisations) leave optional fields empty.

  • Masking coverage of at least 100% of sensitive columns
  • No orphaned child records
  • Empty-value ratio may rise by at most 15%
  • Row counts must match exactly
16 gates it requires
  • POLICY_COVERAGE: every sensitive column is covered by an approved policy
  • MASKING_COMPLETION: masking finished on every covered column
  • REFERENTIAL_INTEGRITY: every reference still points at an existing record
  • SCHEMA_VALIDATION: the output schema matches the source schema
  • DATA_QUALITY: empty-value ratios stay within the preset’s drift limit
  • ROW_COUNT_RECONCILIATION: row counts match the plan within the tolerance
  • ORPHAN_DETECTION: no child record lost its parent
  • PROVENANCE: every row is tagged masked or synthetic
  • MANIFEST: a manifest lists every output table with checksums
  • POLICY_VERSION: the exact approved policy versions are recorded
  • ENGINE_VERSION: the engine version is recorded
  • CHECKSUMS: output checksums are recorded for later verification
  • IDENTITY_CONSISTENCY: linked identifiers got the same pseudonym in every system
  • SOURCE_READ_ONLY: the source was only read, never written
  • EGRESS_GUARD: no row-level data left the agent
  • CONNECTOR_HEALTH: the connectors stayed healthy during the run

Activation status

What is missing before you can activate the Clinical Trials pack yourself:

  • no plan includes it yet
  • the standard agent image does not ship it
  • the control-plane catalogue does not list it
  • the hosted sandbox has no synthetic estate for it

Until then, preview it in the browser demo and download its synthetic asset bundle below.

Tell us you need the Clinical Trials pack or request a feature for it.

Downloads

Version 1.0.0, 74 files (270.2 KB), all synthetic and generated from the pack itself. Every file’s SHA-256 is listed in MANIFEST.json.

Start here (2)
Entity–relationship diagram (2)
Sample schemas (6)
Policy templates (9)
API, CLI, SDK and CI/CD examples (10)
Synthetic sample data (CSV, JSON, Parquet) (43)

Troubleshooting

The reason codes you can meet on the way, with the recovery step. Every code is also in the error-code catalog.

SANDBOX_PACK_NOT_OFFERED — Synthetic estate not offered
A requested synthetic estate (industry pack) is not available in the hosted sandbox. What to do: Start the sandbox with the default estates.
ENTITLEMENT_REQUIRED — Plan does not include this
Your plan does not include this feature or industry pack. What to do: Upgrade in Billing & Plan.
PACK_INTEGRITY_UNVERIFIED — Pack integrity not verified
This pack version was registered without an integrity digest, so it cannot be activated (fail closed). What to do: Ask your operator to re-register the pack catalogue with the current control-plane image (register-pack), then activate again.
PACK_DEPENDENCY_INACTIVE — Required pack not active
This pack depends on another industry pack that is not active for your organization. What to do: Activate the packs this pack depends on first, then activate it again.
AGENT_PACK_MISSING — No agent can run this industry pack
The job's agent does not report the pack (older agents report no packs at all), so the job was not sent. What to do: Upgrade the agent to a release that reports its installed packs and ships this pack, then run the request again.
AGENT_PACK_VERSION_INCOMPATIBLE — Industry pack version differs on the agent
The agent holds a different version of the pack than the one the job was approved for. What to do: Deploy an agent with the pack's active version, or roll the pack back in Industry packs.
AGENT_PACK_INTEGRITY_MISMATCH — Agent pack differs from the catalogue
The agent reports the pack's version with a different integrity digest than the catalogued one, so the job was not sent. What to do: Redeploy the agent from the official signed image for this release, then run the request again.
PACK_TEMPLATES_UNAVAILABLE — Pack templates not registered
This pack version was registered without its policy templates. What to do: Ask your operator to re-register the pack catalogue (register-pack); create policies manually meanwhile.
PACK_TEMPLATE_KEY_REF_REQUIRED — Masking key reference required
A selected template keeps identities linked across systems and needs your masking key reference. What to do: Provide key_ref, e.g. vault://your-vault/tdm-masking-key, then create the drafts again.
PACK_NOT_ENABLED — Industry pack not enabled
The industry pack is not enabled for this tenant. What to do: Enable the pack (if your plan includes it).

Frequently asked questions

Are the Clinical Trials records on this page real?
No. Every record on this page is synthetic, generated from a fixed seed by the pack's own generator; masked values come from the real masking engine. The masking example uses a fixed public sample key; your own data is masked with a key from your secret store.
Can I activate the Clinical Trials pack myself?
This pack is installed and passes DataNivra’s pack conformance kit through the real engine, but it cannot be activated yet: no plan includes it yet, the standard agent image does not ship it, the control-plane catalogue does not list it and the hosted sandbox has no synthetic estate for it. You can explore its synthetic records, masking and scenarios on this page and in the browser demo. Tell us if you need it: demand decides which packs become activatable next.
Which databases and files does the Clinical Trials pack work with?
Verified with this pack version: PostgreSQL and Local files (Parquet / CSV). 17 more connectors are compatible by capability: they support what the pack needs, but have not been verified with this pack yet.
How long does a first certified Clinical Trials dataset take?
Estimates, not guarantees — try the synthetic sandbox: minutes; install (or reuse) the agent: under an hour; connect a source: under an hour; review and approve policies: under an hour; first certified dataset: minutes.
Which test scenarios does the Clinical Trials pack include?
11 runnable scenarios (routine conduct, screen failures, serious adverse events, emergency unblinding and more), plus 1 negative-test scenario kept apart from valid data.
Do Clinical Trials rows leave my network?
No. The DataNivra agent runs inside your environment: it reads the source, masks, subsets, generates and certifies there, and sends only metadata, aggregate counts and evidence to the DataNivra control plane (customer-resident processing, zero raw-production-data egress).

Learn the concepts, then come back to activate

Regulatory context

The Clinical Trials pack covers data that laws and industry rules often treat as sensitive. It supports your privacy and governance programmes by keeping those records inside your environment and producing certification evidence; it does not, by itself, make any system or organisation compliant with any law, regulation or standard.

Everything on this page works without an account. Prefer a conversation? Request a demo (optional). Missing something? Request a feature.